
Diffusion processes and solvers
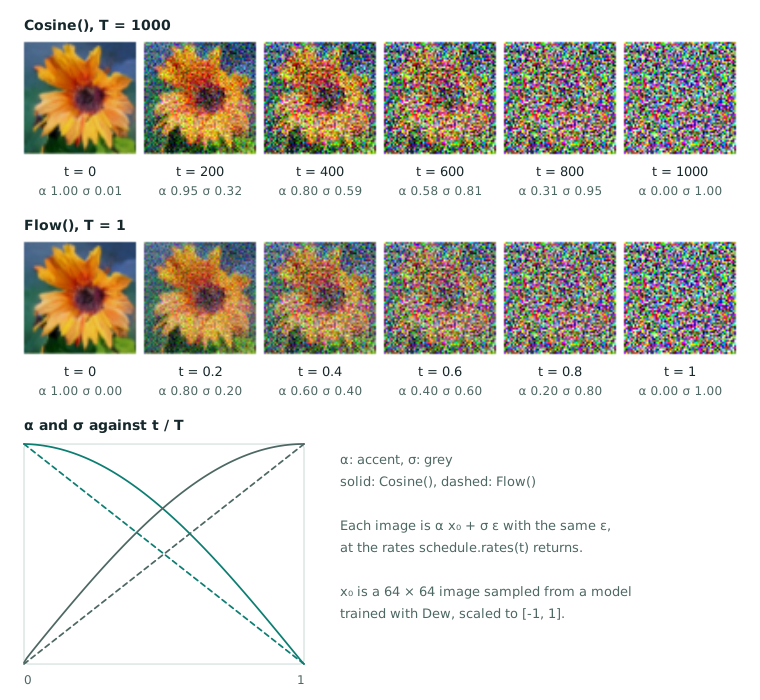
A diffusion model learns to undo noise. Training takes a clean sample , draws a time and a Gaussian , and forms the noisy sample
The network sees and and predicts a quantity from which and can be recovered. Sampling starts from noise at the highest time, and a solver steps through a grid of times down to zero. In Dew, a Process holds every part of this convention that training and sampling must agree on. A preset builds the Process of a published method, and dew.sampling.sample runs a solver over it.
Example
Section titled “Example”import jaximport jax.numpy as jnp
from dew.diffusion.presets import Cosine, Flow
for preset in (Cosine(), Flow()): process = preset() schedule = process.schedule t = jnp.linspace(0, schedule.T, 5) alpha, sigma = schedule.rates(t) times = schedule.sample_t(jax.random.key(0), 4) print(type(preset).__name__, "T =", schedule.T) print(" alpha", " ".join(f"{float(v):.3f}" for v in alpha)) print(" sigma", " ".join(f"{float(v):.3f}" for v in sigma)) print(" training times", " ".join(f"{float(v):g}" for v in times))Cosine T = 1000 alpha 1.000 0.920 0.702 0.378 0.000 sigma 0.006 0.393 0.713 0.926 1.000 training times 789 0 712 373Flow T = 1.0 alpha 1.000 0.750 0.500 0.250 0.000 sigma 0.000 0.250 0.500 0.750 1.000 training times 0.835159 0.883424 0.393268 0.480356Cosine is a table over 1000 discrete steps and draws integer training times uniformly. Flow is continuous on [0, 1], with and , and draws training times from a logit-normal distribution.
Process
Section titled “Process”A Process is a frozen dataclass of four parts:
| Part | What it decides |
|---|---|
| Schedule | and at each time, and how training draws times |
| Prediction transform | What the network outputs: the noise, the clean sample, a velocity, a flow, or the Karras-preconditioned form, and how that converts to and |
| Weighting | How the loss weighs each time: the schedule’s own weight, a P2-style weight, or Min-SNR |
| Sampling schedule | The time grid inference walks, when it differs from training |
Sampling uses four methods of the process. process.noise(key, shape) draws the starting noise at the highest level. process.times(steps) returns the descending grid of times a solver steps through, and process.rates(t, like=x) returns (alpha, sigma) at t, shaped to broadcast against x. process.denoiser(model, params, conditions) wraps a model and its weights into the function a solver calls. That function takes a noisy sample and its time and returns the model’s estimates of the clean sample and of the noise.
Presets
Section titled “Presets”A preset is a frozen dataclass of the numbers that define a published convention. Pass EDM(regime="pixel") or Flow() directly to DiffusionObjective or DiffusionRunConfig(preset=...). They build the process, and the objective’s image task keeps that same process. Call a preset yourself when you want a Process to inspect its schedule or to sample with at a low level.
EDM’s regime chooses the training noise levels, those of Karras et al. (2022) for pixels or EDM2’s for latents. Explicit P_mean and P_std values override the regime. Supplying both also works without a regime, so old run records keep their training distribution. Otherwise an EDM preset without a regime refuses to build, and a run config picks the regime from whether the run has an autoencoder. A run’s run.json stores the preset’s fields, so sampling rebuilds the convention the model was trained with.
| Preset | Convention |
|---|---|
EDM | Log-normal training noise (Karras et al. 2022 for pixels, EDM2 for latents), the EDM preconditioning and weighting, sampled on the rho-spaced Karras grid |
Karras | The EDM preconditioning, trained on noise levels drawn uniformly along the grid it samples on |
Cosine | The cosine beta table with v-prediction; its default P2 weight makes the loss an unweighted loss |
Flow | Rectified flow on the linear path with velocity prediction. Training times follow one of SD3’s densities (Esser et al., 2024): logit-normal (the default), the heavy-tailed mode density, cosmap or uniform. The time is the noise level, as in the paper; Diffusers’ SD3 and Flux training scripts index their timesteps in descending order, so their --logit_mean is the negative of logit_mean here. shift is SD3’s static resolution shift; resolution_shift sets it from the image size instead, as Flux’s exp(mu) of a token count. A run config fills that count from its data on a 16-pixel grid, Flux’s own; a model that tokenizes the image otherwise sets tokens to its count |
JiT | JiT (Li & He, 2025): rectified flow on the linear path where the model predicts the clean sample and the loss scores it in velocity space (VelocityLoss), with sigma floored at t_eps. Training times are the reference’s logit-normal. simple_dit’s patch_bottleneck is JiT’s bottleneck patch embedding for large pixel patches |
MeanFlow | MeanFlow (Geng et al., 2025): rectified flow whose model predicts the average velocity over an interval, reading the interval’s duration beside the time (Process.interval, simple_dit(interval=True)). It trains under MeanFlowObjective (--objective mean_flow on the run config), and one Euler step over the whole grid samples it |
Sqrt | Diffusion-LM (Li et al., 2022): the square-root schedule with the plain loss |
MDLM | Masked diffusion over tokens (Sahoo et al., 2024) on the log-linear schedule, from dew.diffusion.discrete; it takes the vocabulary’s mask_id |
The presets are classes in dew.diffusion.presets. Training and inference can use different schedules; for example, EDM trains on log-normal noise levels and samples on the Karras grid.
MinSNR(gamma) in dew.diffusion replaces a process’s weighting with min-SNR- (Hang et al., 2023). The weight is on the loss, and that value divided by SNR for an prediction or by SNR + 1 for a prediction. The EDM preconditioning computes its loss on , so it takes the cap as it is.
EDM2 (Karras et al., 2024) trains under the EDM preset with its latent regime. Its network is the edm2_unet backbone, built from the magnitude-preserving layers in dew.nn.mp. The backbone matches NVlabs’ UNet (tools/edm2_reference.py), with a text condition in place of the class label. --optim.forced-weight-normalization renormalizes those layers’ weights after every update, as the paper’s forced weight normalization does. --objective.uncertainty 128 on the run config learns the paper’s loss weighting, a head u(sigma) trained beside the model with the loss w / e^u ||D - y||^2 + u. A published task drops that head.
Training aids
Section titled “Training aids”DiffusionObjective(alignment=Alignment(...)) adds representation alignment; on the run config it is the objective’s alignment argument (--objective.alignment '{"layer": "dit_block_7"}'). REPA (Yu et al., 2025) projects the model’s hidden tokens after one layer with an MLP. It scores the projected tokens against a frozen DINOv2’s patch features of the clean image by negative cosine similarity, weighted by weight (REPA’s proj_coeff). Dew’s L2 loss halves the denoising error, so the alignment term is halved with it. iREPA (Singh et al., 2026) sets projector="conv", one 3x3 convolution over the token grid, and spatial_norm=gamma, which z-scores the encoder’s features over space after subtracting gamma times their mean (0.6 in its training script).
Both losses match the official code (tools/repa_reference.py). REPA’s whole training loss, as its train.py composes SILoss, and its gradient in every weight are twice Dew’s. The encoder’s input goes through REPA’s and iREPA’s DINOv2 preprocessing: divide by 255, apply ImageNet’s normalization, and resize bicubically to 224 for a 256-pixel image with resolution=224. The projector trains beside the model and the encoder’s weights stay frozen, and a published task drops both.
The aligned tokens must lie on the encoder’s patch grid in raster order. For REPA’s setup on a 256-pixel run, a latent DiT of patch 2 has 16x16 tokens, which the default source, source="facebook/dinov2-base", reads at resolution=224 (16x16 patches of 14 pixels). layer="dit_block_7" aligns after the eighth block of simple_dit. Any other encoder is a model record, encoder, such as a SigLIP or MAE tower, or a custom module: its weights are the starting tree’s REPRESENTATION when it holds them, and source’s otherwise, which loads a DINOv2 checkpoint (dew.nn.autoencoders.rae.load_dinov2).
end_to_end=EndToEnd() beside an alignment adds REPA-E (Leng et al., 2025), which tunes the run’s KL autoencoder together with the model. The autoencoder trains on REPA-E’s published loss (configs/l1_lpips_kl_gan.yaml): its L1 reconstruction, LPIPS on VGG16 at its published weights (dew.eval.LPIPSNetwork), the KL, and 0.1 times a PatchGAN’s generator term, plus 1.5 times the alignment loss of its latent as the frozen model reads it. The PatchGAN (PatchDiscriminator, REPA-E’s NLayerDiscriminator) trains in the same step on the hinge loss of the images against the reconstruction, and a pretrained one can be given to init; each of the two terms leaves its network out at weight 0. The model (with its projector), the autoencoder and the PatchGAN each step on their own copy of the run’s optimizer, with their own clipping and moments, as REPA-E’s three AdamWs do. The model trains on the detached latent, normalized by a batch norm without affine parameters. That norm’s running statistics replace the autoencoder’s fixed latent scale. A saved run’s task decodes with the tuned autoencoder and these statistics, scaling by the reciprocal square root of the running variance without the norm’s epsilon, as REPA-E’s extract_latents_stats does.
The regularizer, the batch norm and a whole step match REPA-E’s code. tools/repae_reference.py runs train_repae.py’s loop body as published, LPIPS and the PatchGAN included, and tools/lpips_reference.py runs REPA-E’s PerceptualLoss. Against them, Dew’s step gives the same autoencoder and discriminator gradients and running statistics, and half the model’s gradient, because Dew halves its L2 loss.
simple_dit’s routes is TREAD’s token routing (Krause et al., 2025), which applies during training only. Each (ratio, start, end) makes a random ratio of the tokens skip blocks start to end. Those tokens rejoin afterwards with the values they had before start, so the skipped blocks compute on fewer tokens. The gather and scatter match CompVis/tread’s Router (tools/tread_reference.py), and sampling runs every token through every block.
Few-step generators
Section titled “Few-step generators”MeanFlowObjective trains the average velocity u(z_t, r, t) through the MeanFlow identity u = v - (t - r) du/dt. One jax.jvp through the model takes the derivative along the flow. The training-time guidance mixes the sample’s velocity with the model’s own unconditional and conditional velocities (omega, kappa), and each row’s squared error is weighted adaptively (norm_p, norm_eps).
As in the reference, the condition is dropped on the first rows of a batch, which are the instantaneous rows, and a draw at unconditional_prob decides how many. The loss and its gradient match Gsunshine/meanflow’s forward on the reference’s own draws (tools/meanflow_reference.py). On an interval process, sample gives the model the interval to the next grid point at every step, so steps=2 is one step from noise to data.
MeanFlow’s and sCM’s losses differentiate the model in time, so the model’s time embedding has to change slowly with time. With simple_dit’s default Fourier scale of 16, applied to a flow’s model time (sigma times 1000), it changes too fast. A MeanFlow run config sets time_scale=0.002 when the model config names no scale, and sCM distillation refuses a teacher whose model turns faster unless it distills with DMD alone (consistency_weight=0).
On a 2-D two-class toy, a ring of eight Gaussians trained with these objectives on a one-token simple_dit (RTX 4080), MeanFlow at scale 16 diverged after 8,000 steps, and the sCM student reached 11% class accuracy in one step. At time_scale=0.002, MeanFlow reached 99% in one step and 100% in two, and the rCM student reached 98.6% in one step, from a teacher that needs about 32 Euler steps for 99.9%.
ShortcutObjective (Frans et al., 2025) trains a velocity conditioned on its step size; on the run config it is --objective shortcut, under the Shortcut preset. Most rows are flow matching at the finest step, 1 / sections. One row in bootstrap_every trains self-consistency at dyadic levels, so that one step of 2d equals two steps of d from the EMA weights.
The path is the reference’s, (1 - (1 - 1e-5) t) * noise + t * data, whose noise keeps a factor of 1e-5 at the data end, and the loss is its mean squared error. The loss and its gradient match kvfrans/shortcut-models’ get_targets and the loss in its update (tools/shortcut_reference.py). The reference’s flow rows reuse the batch’s first images, as its self-consistency rows do. Dew gives every row its own image, and each row’s loss still has the same distribution as the reference’s.
ConsistencyDistillationObjective is rCM (Zheng et al., 2025), set as --objective rcm --teacher-run <run directory> on the run config. It distills a saved flow run into a few-step student on TrigFlow. The teacher’s model is the student’s without its adapter, or the model record teacher, and its weights are the starting tree’s TEACHER when it holds them, as a saved student’s does, else those the teacher run published; LADD’s teacher is read the same way, and guidance distillation’s is the teacher run’s whole objective. The sCM loss (Lu & Song, 2025) pulls the student toward the teacher ODE’s tangent, which comes from one jax.jvp through the student. The DMD2 loss (Yin et al., 2024) moves the student’s few-step samples along the difference between a fake score, trained on those samples, and the teacher. consistency_weight=0 keeps only DMD2, and dmd_weight=0 keeps only sCM. The losses match NVlabs/rcm’s own methods on their draws (tools/rcm_reference.py).
As in rCM, the student and the fake score each step with their own copy of the optimizer, on their own updates (Several networks, several optimizers). The EMA averages the student’s updates at the student’s own count, and ema_decay=power_decay(0.1) (dew.averaging) is rCM’s power EMA. After ten updates through Trainer, both networks, the EMA and both Adams’ moments are where rCM’s own training loop puts them. The phases alternate update by update, each read off the committed updates (step.updates), so every microbatch an update accumulates is of its phase. The student samples with Consistency.
cuDNN’s and the TPU’s fused attention define only reverse-mode derivatives. So inside dew.nn.attention.forward_mode_attention(), where the JVP runs, each attention call keeps the fused kernel’s value and takes its tangent from the reference path. On an RTX 4080 the cuDNN tangent matches the XLA kernel’s to bf16 rounding.
GuidanceDistillationObjective distills a saved run’s classifier-free guidance into a model that reads the guidance scale as an input of its conditioning, as FLUX.1 [dev] does. On the run config it is --objective guidance_distillation --teacher-run <run directory>. This is stage one of Meng et al. (2023). Each row draws a scale w, and the student regresses its raw output onto the teacher’s u + w (c - u) on the same noised sample. FLUX.1 [dev] has no published training code for its guidance embedding, so the tests check the loss against the paper’s equation. A saved student samples one branch at its conditioner’s guidance value.
AdversarialDistillationObjective trains a few-step student with LADD’s projected discriminator (Sauer et al., 2024); on the run config it is --objective ladd --teacher-run <run directory> --objective.feature-layers .... Both the clean predictions and the reference samples are renoised, and the frozen teacher’s token grids go into StyleGAN-T heads with spectral normalization, local batch normalization and projection conditioning. The hinge losses train each side with the other side’s gradient stopped. ADD’s R1 penalty regularizes the heads, and distillation_weight adds ADD’s alpha-weighted, summed squared distance toward the teacher’s denoising (Sauer et al., 2023). LADD drops that term for synthetic data. ADD’s DINOv2 discriminator is not implemented.
Neither paper publishes training code, so tools/ladd_reference.py writes one step as an oracle in torch: the papers’ equations around StyleGAN-T’s DiscHead and DiT’s timestep embedding, run as published. Dew’s loss, every gradient and the heads’ spectral state match it on Dew’s own draws. Two choices are Dew’s own, because the papers make neither. The student and the heads train in the same step, where StyleGAN-T alternates a generator step and a discriminator step. The spectral norms iterate once per step on the real pass, and the other passes read that iteration without storing their own.
The CIFAR-10 runs below use 32-pixel images, a flow simple_dit teacher (width 256, six blocks, 3,000 training steps), and FID-5k. Teacher columns give one-/four-/25-step Euler FID with CFG 1.5. Student columns use Consistency, without sampling-time CFG.
| Setup | Student steps | Seeds | One-step FID | Four-step FID | Teacher FID (1 / 4 / 25 steps) |
|---|---|---|---|---|---|
| RTX 4080, prototype MLP heads, real data, several learning rates and renoising levels | 1,500–3,000 | 0 | 319–365 | — | 316 / 103 / 90 |
| RTX 4080, StyleGAN-T heads + R1, real data, lr 1e-5, batch 64, no distillation | 4,000 | 0 | 268 | 237 | 316 / 103 / 90 |
| Same | 4,000 | 1 | 283 | 292 | 316 / 103 / 90 |
| Same | 4,000 | 2 | 319 | 283 | 316 / 103 / 90 |
| RTX 4080, StyleGAN-T heads + R1, ADD distillation weight 2.5 | 2,500–4,000 | 0 | 430–437 | — | 316 / 103 / 90 |
| A100, StyleGAN-T heads + R1, synthetic teacher samples, lr 1e-5, batch 128, no distillation | 20,000 | 0 | 243.01 | 168.87 | 310.34 / 102.85 / 85.54 |
| Same | 20,000 | 1 | 216.91 | 160.52 | 310.34 / 102.85 / 85.54 |
| Same | 20,000 | 2 | 254.73 | 143.26 | 310.34 / 102.85 / 85.54 |
Every A100 seed improved one-step FID by 18 to 30% over that run’s teacher at one step, and none reached the teacher’s four-step FID. Those runs used the paper’s high-noise renoising and resumed between 4,000-step segments. The ADD distance dominated the short real-data runs. Dropping it follows LADD’s synthetic-data recipe and does not change ADD’s equation.
A separate two-class 2-D toy exposed the renoising sensitivity in the prototype heads (RTX 4080, one seed, 3,000 steps):
| Setup | One-step class accuracy | Log-density | Mode coverage |
|---|---|---|---|
| Paper renoising mean 1, std 1 | 53% | — | Discriminator near chance |
| Renoising mean -2, std 1, distillation weight 2.5, 256-wide prototype heads | 99.6% | 0.49 | All modes |
| Same lower renoising, no distillation or 64-wide prototype heads | — | — | One mode per class |
These runs check that training works at small scale; they do not reproduce the papers’ image-quality results.
Solvers
Section titled “Solvers”sample(denoise, x_T, steps, solver=..., key=...) runs a solver from the highest time to zero. denoise is process.denoiser(model, params, conditions), which calls the model and converts its output into estimates of and . This samples from an untrained DiT with two solvers; only the shapes are meaningful:
from dew.nn.backbones.dit import SimpleDiTfrom dew.sampling import DDIM, Euler, sample
process = Flow()()model = SimpleDiT(patch_size=4, emb_features=16, num_layers=1, num_heads=2,                  mlp_ratio=2, dtype=jnp.float32, attention_impl="xla")params = model.init(jax.random.key(0), jnp.zeros((1, 8, 8, 3)), jnp.zeros((1,)))denoise = process.denoiser(model, params, conditions={})x_T = process.noise(jax.random.key(1), (2, 8, 8, 3))print(process.times(5))for solver in (Euler(), DDIM()):    x_0 = sample(denoise, x_T, 5, solver=solver, key=jax.random.key(2))    print(type(solver).__name__, x_0.shape, x_0.dtype)
[1. 0.75 0.5 0.25 0. ]Euler (2, 8, 8, 3) float32DDIM (2, 8, 8, 3) float32sample steps through the steps points of process.times(steps) and returns the model’s clean prediction at the last point. The whole loop is one jax.lax.scan, so it compiles once, and each step’s noise comes from key folded with the step index. The solver only affects sampling, so you can change it without retraining.
The classic integrators are DDPM, DDIM, Euler, EulerAncestral, Heun, RK4, and MultiStepDPM, a third-order finite-difference integrator in sigma space that keeps the last three noise estimates. A second group follows the Diffusers schedulers and reproduces the Diffusers 0.34.0 trajectories recorded by tools/diffusers_reference.py:
DPMSolverMultistepcovers every algorithm, order and second-order form ofDPMSolverMultistepScheduler, and the EDM scheduler’s update over the EDM process.DPMSolverSinglestep,DPMSolverSDE,DEIS,UniPC,PNDM,LMS,KDPM2(plain and ancestral) andTCD.Consistency, used with theConsistencyBoundaryprediction transform, for latent consistency models.
FlowSDE is Flow-GRPO’s Euler-Maruyama solver on a rectified-flow process.
Heun is Algorithm 2 of Karras et al. (2022), and its s_churn, s_tmin, s_tmax and s_noise set that algorithm’s stochasticity. Inside [s_tmin, s_tmax], each step first adds fresh noise to raise sigma by the factor 1 + min(s_churn / N, sqrt(2) - 1), then takes the Heun step from the raised sigma. It matches NVlabs’ edm_sampler (tools/edm_reference.py). The churn changes sigma directly, so it needs a variance-exploding process, and a step that would raise sigma past the schedule’s top is refused.
MultiStepDPM and DPMSolverMultistep are different solvers, despite the similar names. DPMSolverSDE is the solver of DPMSolverSDEScheduler, and it is separate from the SDE algorithms of DPMSolverMultistep. Each of its intervals takes two ancestral steps, and both draw noise from one keyed Brownian bridge over the schedule’s positive sigma range, so the two draws are nested increments of a single path.
DDPM(variance="large") uses the wider published posterior variance, the beta of the variance-preserving forward step. That beta is zero wherever alpha is one, so on a variance-exploding grid DDPM would add no noise at all, and it refuses such a grid. Neither variance adds noise on the step whose own time is the schedule’s zero.
For DPM-Solver++ 2M without any lowering of order at the end, use DPMSolverMultistep(order=2, algorithm="dpmsolver++", solver_type="midpoint", lower_order_final=False, euler_at_final=False). The default lower_order_final=True follows Diffusers. With fewer than 15 steps, the last step is first order and the one before it at most second order. A solver’s init takes (x_T, times, process, key=key) with a concrete time grid, so an invalid pair of endpoints fails before the compiled loop starts.
Source clipping and dynamic thresholding are part of SourceLimitedPrediction, the process’s prediction conversion, and no solver applies them. So a solver that reads the clean prediction twice sees the limited value both times.
Guidance
Section titled “Guidance”CFG(scale, interval=(0.0, 1.0), rescale=0.0) is classifier-free guidance. At each step the model predicts once with the condition and once without it, and the guided prediction is uncond + scale * (cond - uncond). Outside interval the scale drops to 1 (Kynkäänniemi et al., 2024). rescale is Diffusers’ guidance_rescale (Lin et al., 2023), which pulls the guided output toward the conditional output’s standard deviation; rescale=0 leaves the output unchanged.
The interval is given in fractions of the sampling steps and includes both ends. Step i of N is guided when start <= i / N <= stop, and the final denoise counts as step N. Each step decides once, and every evaluation within it, such as Heun’s corrector or a midpoint, uses that decision. This matches the paper’s own sampler, which tests/test_guidance.py runs against; its guidance_interval=[a, b] over N steps is interval=(a / N, b / N) here. A Diffusers guider’s start and stop guide its steps [int(start * N), int(stop * N)), which is interval=(int(start * N) / N, (int(stop * N) - 1) / N) here. Every guidance rule below takes interval the same way.
Guidance is applied to the model’s raw outputs, and the process then converts the guided output once, in the same order as published pipelines. So a nonlinear conversion never sees the two branches separately. For one model to make both the conditional and the unconditional prediction, train it with some conditions blanked. DiffusionObjective(unconditional_prob=...) replaces the condition with its empty value on that fraction of rows, 12% by default.
Three other guidance rules can take the place of CFG in sample and TextToImage:
APG(scale, eta=1.0, norm_threshold=15.0, momentum=0.0)is adaptive projected guidance (Sadat et al., 2025). It averages the directioncond - uncondover sampling steps withmomentum, clips its norm atnorm_threshold, and scales its component parallel to the conditional output byeta. Witheta=1, no clipping and no momentum, it equalsCFG. It matches Diffusers’AdaptiveProjectedGuidanceover a complete trajectory, including the interval mapping above. When guidance is off, the momentum average stays unchanged, as in Diffusers.CFGPlusPlus(scale)is CFG++ (Chung et al., 2025), withscalein [0, 1]. It guides the clean prediction, and each step renoises with the unconditional noise prediction. Only solvers that step from the(x_0, epsilon)pair, such asDDIM, follow its trajectory.Autoguidance(scale, model)guides with a weaker model of the same task, run under the same condition (Karras et al., 2024). The guided output isguide + scale * (model - guide). The guide’s variables go underguidein the denoiser’s variables. It matches NVlabs/edm2’sedm_sampler(gnet=...).
Text to image
Section titled “Text to image”TextToImage in dew.inference combines the text encoder, the denoising loop and, for latent models, the decoder. objective.pipeline(state) builds one from a trained objective, and TextToImage.from_run(directory) rebuilds one from a saved run.
For Stable Diffusion and SDXL checkpoints, dew.pipeline(source) rebuilds the source’s own scheduler, so you do not pick a solver by name. It supports the source’s clipping, thresholding and timestep spacing, and the Karras, exponential and beta grids where the corresponding scheduler has them. DPM-Solver multistep and UniPC files with use_flow_sigmas, which flow pipelines such as SANA and Wan ship, follow the shifted rectified-flow path and read the model output as velocity. An unsupported combination raises an error, and Dew does not fall back to different defaults. The scheduler checks compare tiny synthetic trajectories against Diffusers and do not measure image quality. Supported models lists the pipelines that load.