Skip to content

Train models with JAX and Flax.

Language models, diffusion and JEPA, on one device or a mesh.

uv pip install "dew-ml @ git+https://github.com/AshishKumar4/dew"

Run it

train.py
import itertools
import jax
import numpy as np
import optax
from dew import Dataset, Trainer, models
from dew.data import ByteTokenizer
from dew.objectives.lm import LMObjective
from dew.sampling import Sampling, generate
tokenizer = ByteTokenizer()
text = tokenizer.encode("dew trains jax models. " * 3)
batch = {"text": np.tile(np.asarray(text[:65], np.int32), (8, 1))}
data = Dataset(train=lambda partition: itertools.repeat(batch),
val=None, records=8, batch=8)
model = models.build(
"causal_transformer", vocab_size=tokenizer.vocab_size,
emb_features=64, num_layers=2, num_heads=4,
mlp_features=256, max_seq_len=128)
objective = LMObjective(model, seq_len=64)
trainer = Trainer(objective, optax.adamw(3e-3),
key=jax.random.key(0))
state = trainer.fit(data, steps=100, log_every=25)
prompt = [tokenizer.encode("dew")]
out = generate(model, state.params, prompt, max_new_tokens=40,
key=jax.random.key(1),
sampling=Sampling(temperature=0))
print(tokenizer.decode(out.tokens[0]))
python train.py
Training from step 0 to 100 on {'data': 1, 'expert': 1, 'fsdp': 1, 'tensor': 1, 'sequence': 1, 'stage': 1} (1 process(es))
step 25: loss 0.0336
step 50: loss 0.0107
step 75: loss 0.0070
step 100: loss 0.0053
Goodput: first step after 6.81 s, 23.4% of the wall time in steps
dew trains jax models. dew trains jax model

Recorded on the CPU of a Colab runtime, 2 vCPUs, JAX 0.11.2, Dew 60d49d2, 2026-09-24, 19 s.

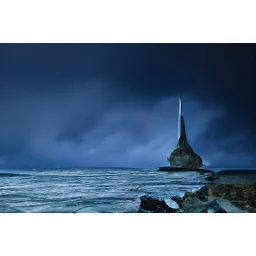
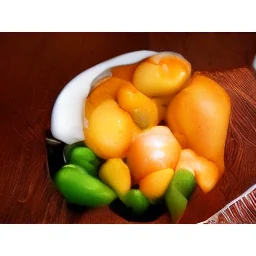
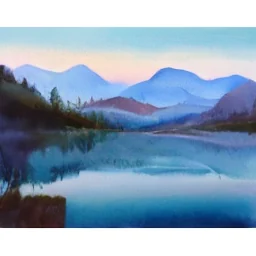
Text to image

“a watercolor painting of a mountain lake at sunrise”
“a lighthouse on a rocky coast under a stormy sky”
“a bowl of fresh fruit on a wooden table”

A 71M-parameter model trained with FlaxDiff, sampled with Dew.

Language models

05-train-a-language-model.ipynb
from dew.sampling import Sampling, generate
prompt = jnp.asarray([tokenizer.encode(PROMPT)], jnp.int32)
out = generate(model, state.averaged, prompt, max_new_tokens=MAX_NEW_TOKENS,
key=jax.random.key(1), sampling=Sampling(temperature=0.8, top_k=40))
print(tokenizer.decode(out.tokens[0]))
ROMEO:
Tut Tybalt, Gracious fazous to deparal,
Your bring shall be find that is in the sign,
Why both his hardy nundrest to an all ment.

RICHMOND:
Let must be, my lord, if you that day:
But yea, sir, then time and with himself;
Her oft protection to his death to the supper your
mother married to men.

HERMIONE:
And not that his by the duke a heaveness.

Third I change it another canst thou beast;
When

Released weights

08-load-a-pretrained-decoder.ipynb
import torch
from transformers import AutoModelForCausalLM
hf_model = AutoModelForCausalLM.from_pretrained(EXPORT_DIR, dtype=torch.float32)
with torch.no_grad():
hf_next = int(hf_model(input_ids=torch.tensor(np.asarray(prompt))).logits[0, -1].argmax())
dew_next = generate(model, state.params, prompt, max_new_tokens=1,
key=jax.random.key(0), sampling=Sampling(temperature=0.0))
dew_next = int(dew_next.tokens[0, -1])
print("transformers:", hf_next, repr(tokenizer.decode([hf_next])))
print("dew: ", dew_next, repr(tokenizer.decode([dew_next])))
transformers: 198 '\n'
dew:          198 '\n'

Meshes

07-scaling-on-many-devices.ipynb
sharded = Trainer(objective, optax.adamw(1e-3), key=jax.random.key(0),
mesh=MeshSpec(fsdp=8), layout=Layout(min_shard=1),
checkpoints=Checkpoints(f"{RUN_DIR}/sharded"))
sharded_state = sharded.fit(data, steps=STEPS, log_every=10)
describe(sharded_state)
Training from step 0 to 20 on {'data': 1, 'expert': 1, 'fsdp': 8, 'tensor': 1, 'sequence': 1, 'stage': 1} (1 process(es))
step 10: loss 3.5792
step 20: loss 2.6488
Goodput: first step after 4.97 s, 15.0% of the wall time in steps
spec: P('fsdp',)
  cpu:0: rows slice(0, 32, None), local shape (32, 64)
  cpu:1: rows slice(32, 64, None), local shape (32, 64)
  cpu:2: rows slice(64, 96, None), local shape (32, 64)

Tutorials

  1. 01Diffusion from scratchGPU
  2. 02Image diffusionGPU
  3. 03Text to imageGPU
  4. 04SamplersGPU
  5. 05Language modelGPU
  6. 06I-JEPAGPU
  7. 07Many devicesCPU
  8. 08Pretrained decodersGPU